

3.3: Data Ingestion Techniques
- Page ID
- 48037

\( \newcommand{\vecs}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\( \newcommand{\vecd}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash {#1}}} \)
\( \newcommand{\dsum}{\displaystyle\sum\limits} \)
\( \newcommand{\dint}{\displaystyle\int\limits} \)
\( \newcommand{\dlim}{\displaystyle\lim\limits} \)
\( \newcommand{\id}{\mathrm{id}}\) \( \newcommand{\Span}{\mathrm{span}}\)
( \newcommand{\kernel}{\mathrm{null}\,}\) \( \newcommand{\range}{\mathrm{range}\,}\)
\( \newcommand{\RealPart}{\mathrm{Re}}\) \( \newcommand{\ImaginaryPart}{\mathrm{Im}}\)
\( \newcommand{\Argument}{\mathrm{Arg}}\) \( \newcommand{\norm}[1]{\| #1 \|}\)
\( \newcommand{\inner}[2]{\langle #1, #2 \rangle}\)
\( \newcommand{\Span}{\mathrm{span}}\)
\( \newcommand{\id}{\mathrm{id}}\)
\( \newcommand{\Span}{\mathrm{span}}\)
\( \newcommand{\kernel}{\mathrm{null}\,}\)
\( \newcommand{\range}{\mathrm{range}\,}\)
\( \newcommand{\RealPart}{\mathrm{Re}}\)
\( \newcommand{\ImaginaryPart}{\mathrm{Im}}\)
\( \newcommand{\Argument}{\mathrm{Arg}}\)
\( \newcommand{\norm}[1]{\| #1 \|}\)
\( \newcommand{\inner}[2]{\langle #1, #2 \rangle}\)
\( \newcommand{\Span}{\mathrm{span}}\) \( \newcommand{\AA}{\unicode[.8,0]{x212B}}\)
\( \newcommand{\vectorA}[1]{\vec{#1}} % arrow\)
\( \newcommand{\vectorAt}[1]{\vec{\text{#1}}} % arrow\)
\( \newcommand{\vectorB}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\( \newcommand{\vectorC}[1]{\textbf{#1}} \)
\( \newcommand{\vectorD}[1]{\overrightarrow{#1}} \)
\( \newcommand{\vectorDt}[1]{\overrightarrow{\text{#1}}} \)
\( \newcommand{\vectE}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash{\mathbf {#1}}}} \)
\( \newcommand{\vecs}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\(\newcommand{\longvect}{\overrightarrow}\)
\( \newcommand{\vecd}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash {#1}}} \)
\(\newcommand{\ket}[1]{\left| #1 \right>}\)
\(\newcommand{\bra}[1]{\left< #1 \right|}\)
\(\newcommand{\braket}[2]{\left< #1 \vphantom{#2} \right| \left. #2 \vphantom{#1} \right>}\)
\(\newcommand{\braopket}[3]{\left< #1 \vphantom{#2}\vphantom{#3} \right| #2 \vphantom{#1}\vphantom{#3} \left| #3 \vphantom{#1}\vphantom{#2} \right>}\)
\(\newcommand{\qmvec}[1]{\mathbf{\vec{#1}}}\)
\(\newcommand{\op}[1]{\hat{\mathbf{#1}}}\)
\(\newcommand{\expect}[1]{\langle #1 \rangle}\)
\(\newcommand{\dfn}[1]{\emph{\textbf{#1}}}\)
Data Ingestion Techniques
After data has been collected from source systems, the next major step is to ingest that data into target systems (data lakes, data warehouses, or real-time analytics platforms). Data ingestion can happen in different modes and with different architectures. In this section, we explore key data ingestion techniques and patterns [1]:
-
Batch vs. Streaming Ingestion – the timing and frequency model for moving data.
-
ETL (Extract, Transform, Load) – a traditional batch-oriented ingestion and transformation pipeline.
-
ELT (Extract, Load, Transform) – a modern twist where loading precedes transformation, often used with cloud data lakes/warehouses.
-
CDC (Change Data Capture) – techniques for ingesting only changes (deltas) from source systems.
-
Message Queues and Streaming Platforms – using intermediaries like Kafka or RabbitMQ to facilitate ingestion.
These techniques are not mutually exclusive; they often can be combined. For instance, CDC can be used to achieve streaming ingestion from databases, and message queues might be part of both streaming and batch architectures for decoupling. We will discuss each in turn.
3.3.1 Batch vs. Streaming Ingestion
One fundamental aspect of data ingestion is when and how often data is moved. This leads to the distinction between batch processing and streaming (real-time) processing [3]:
-
Batch Ingestion: In batch processing, data is collected over a period of time and then ingested in bulk as a “batch” at specific intervals. For example, an ETL job might run every night at 2:00 AM to fetch all the previous day’s transactions and load them into a warehouse. Batches could be hourly, daily, weekly, or any frequency, but the key is that the data accumulates and is processed as a whole unit. Batch ingestion is known for its simplicity and reliability. It also often imposes less overhead on systems because processing can be scheduled during off-peak hours. Many traditional data warehouses and business intelligence reports rely on daily batch updates – meaning the data is current up to the last batch run.
Advantages: Batch processes can be optimized and tuned for large throughput. They are easier to design and manage in many cases, because you deal with a fixed dataset in each run. If something fails, you can re-run the batch. They also avoid constant load on source systems; instead of querying continuously, you do it once per interval. Batch windows allow using system resources when they’re less needed for transactional work (e.g., at midnight the user traffic is low, so we use the database for heavy reads then). “Batch processing is known for its simplicity, reliability and minimal impact on system performance, as it can be scheduled for off-peak hours,”. Batch is suitable for scenarios where real-time updates are not critical – for instance, a weekly sales report or monthly accounting ledger.
Disadvantages: The primary downside is latency. If you only ingest data once a day, then any analysis will be at best as recent as yesterday’s data – not suitable for dynamic decision-making or applications that need up-to-the-minute information. In today’s fast-paced environment, many business needs (fraud detection, customer personalization, IoT monitoring) cannot wait for the next batch – they need data within seconds or minutes. Another issue is batch size: as data volume grows, batch jobs might take longer to run, potentially spilling into working hours or failing to complete.
-
Streaming (Real-Time) Ingestion: Streaming ingestion means continuously ingesting data as soon as it is available, often in small chunks or even one record at a time. Rather than wait and collect a bunch of events, a streaming pipeline processes each event (or micro-batches of seconds or milliseconds) and pushes it through to storage or analysis in near real-time. For example, a streaming pipeline might ingest a clickstream from a website, processing each user click event within seconds and updating dashboards or triggering alerts immediately.
Advantages: The main benefit is freshness and low latency – you have the most up-to-date data possible. This enables use cases like real-time analytics, live dashboards, immediate anomaly detection, etc. Businesses can react quickly (e.g., detect a fraudulent transaction as it happens, rather than a day later). Streaming also can handle continuous high-volume data by distributing processing over time (not lumping it into one big batch). Modern stream processing frameworks (like Apache Kafka, Flink, Spark Streaming) can scale horizontally to handle massive event flows. For IoT and time-sensitive data (stock prices, sensor alerts), streaming ingestion is essential.
Disadvantages: Streaming systems are generally more complex to build and maintain. They demand robust infrastructure that can run 24/7 without downtimes, and they often require considerations like exactly-once processing, ordering of events, and fault tolerance in a distributed system. They also can put more continuous load on networks and systems (since data is moving constantly). Additionally, analyzing streaming data sometimes calls for a different approach (aggregating windows of events, etc.). Resource usage is a consideration – to get real-time results, you might need more computing resources running all the time, whereas a batch job uses resources briefly. As IBM notes, real-time and stream processing “demand significant computing power and network bandwidth”.
It’s worth noting a middle ground known as micro-batching, which processes very small batches at high frequency (say, every minute or every few seconds). This can sometimes simplify design (treating data in tiny batches instead of true record-by-record streaming) while still achieving near-real-time freshness. One definition of microbatching can be defined as “ingesting data in small, frequent batches, providing near real-time updates without the resource constraints of full real-time processing”.
Choosing Batch vs Streaming: Many organizations employ a hybrid known as the Lambda architecture, which combines a batch layer (for completeness and accuracy using all data) with a speed layer (for real-time partial results). For instance, a daily batch pipeline might compute a thorough analysis on all data, while a streaming pipeline feeds a dashboard with the newest events. The two outputs are reconciled when the batch results catch up. Another approach, the Kappa architecture, advocates using streaming for both real-time and reprocessing historically, eliminating the batch layer by treating all data as a stream.
The choice depends on needs: if you can accept latency of a few hours and want simpler infrastructure, batch is fine. If you need instant data and are willing to manage the complexity, streaming is the way. Often, it’s not either/or; critical data might be ingested via streaming, whereas less critical might still be batch. For example, a bank might stream credit card transactions for fraud checks (immediate), but batch-ingest end-of-day account balances for a nightly report.
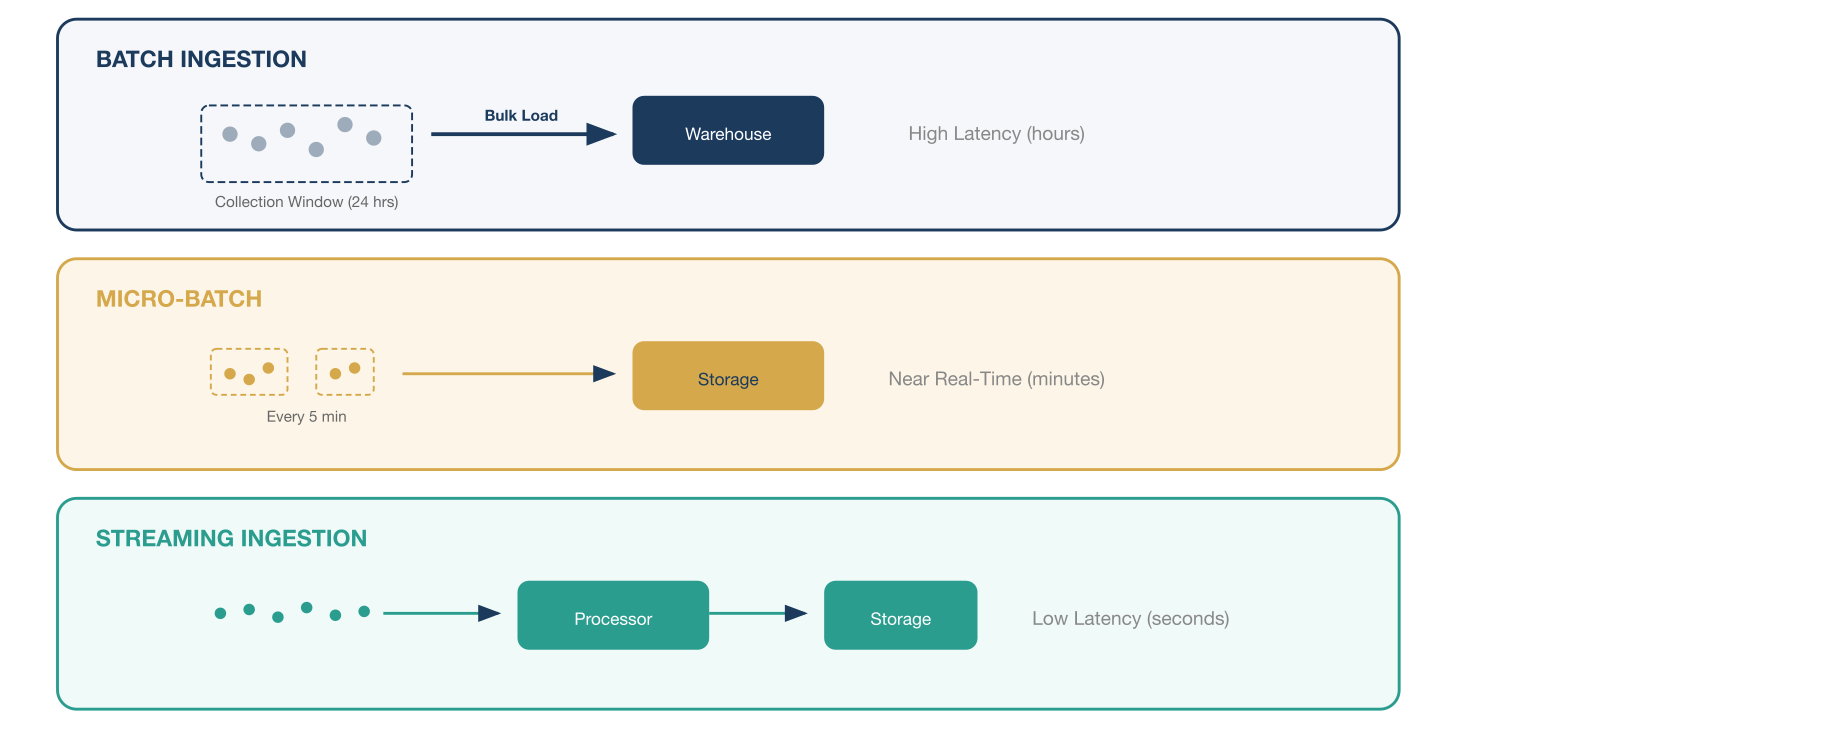
In practice, streaming and batch can complement each other. As one article puts it, “Hybrid data ingestion combines aspects of both real-time and batch ingestion”, such as a Lambda architecture where a speed layer handles immediate updates while a batch layer does periodic reconciliation. This approach can give the best of both worlds: immediacy and accuracy.
3.3.2 ETL (Extract, Transform, Load)
ETL stands for Extract, Transform, Load – a long-standing paradigm in data warehousing and ingestion pipelines. In an ETL process, data from source systems is first extracted (pulled out of the source, such as reading from a database or flat file), then transformed (cleaned, aggregated, reshaped, etc. while in transit or in a staging area), and finally loaded into the target database or warehouse in its final form.
How ETL Works: Historically, ETL jobs would extract data from multiple operational databases, transform it to fit a unified schema and apply business logic (e.g., converting all date formats to a standard, merging several source fields into one, filtering out certain records), and then load it into a data warehouse. The transformation step often took place on an ETL server or in an intermediate staging database. Once transformed, the clean data is loaded into the warehouse’s tables for use by analysts. ETL jobs can be implemented with tools (Informatica, Talend, Microsoft SSIS, etc.) or custom scripts. They often run as batch processes (nightly or hourly).
When to use ETL: ETL is ideal when you need to enforce complex transformations and data quality rules before the data lands in the warehouse. Many older data warehouses (especially on-premises ones) expected the data to match a predefined schema (e.g., star schema) upon load, so doing transformation first was necessary. ETL is also useful for compliance – if there’s sensitive data, you can redact or mask it during transformation before loading to the target (Integrate.io, 2025 notes that ETL can help remove sensitive information upfront to satisfy regulations like GDPR. ETL processes have been around for decades and are well-understood; there's a lot of expertise and tooling, making it relatively straightforward to find solutions and talent for building ETL pipelines.
Benefits: As mentioned, one benefit is data quality and compliance control early. Since transformation happens on the fly, the target system only gets clean, standardized data. This can also mean lower storage needs on the data warehouse because you’re not storing raw duplicative data, only the refined result. ETL can do complex joins and calculations before loading, ensuring the warehouse is optimized for queries (often the warehouse ends up with summary tables or schemas suited to analytics). Another benefit historically was performance: transforming data in a powerful ETL server or using the source system’s power and then loading a smaller result to the warehouse reduced the workload on the warehouse. ETL was the default when warehouses were expensive and less scalable, so you did work outside of them.
Drawbacks: The biggest limitation of ETL is lack of flexibility and longer time-to-data. Because you transform first, any new question that requires data in a different form means you need to update the ETL pipeline and re-run it. If you didn’t bring a particular data attribute into the warehouse because it wasn’t needed in your defined schema, you can’t easily query it later without changing the ETL. It also can slow down ingestion – data isn’t available until fully transformed. If transformation is heavy, it can create bottlenecks. ETL also usually implies a staging area to hold the intermediate data (Integrate.io describes ETL moving data to a staging area for transform, adding complexity. With today’s very large data sets, doing transformation on-the-fly can become computationally expensive (especially if using an external ETL server vs. the massively parallel processing of modern cloud warehouses).
To summarize, ETL is a robust approach when you have well-defined transformation needs and want the target to have only clean, analysis-ready data. It remains widely used for integrating operational data into enterprise data warehouses, particularly for structured data sources.
3.3.3 ELT (Extract, Load, Transform)
ELT flips the order: Extract, Load, Transform. In an ELT pipeline, data is first extracted from sources and loaded in its raw or minimally processed form into the target system (often a data lake or a cloud data warehouse). Once the data is in the target, the transformations are done there – meaning using the computational power of the target system (like running SQL transform queries in the warehouse, or using big data processing engines on the lake).
This approach has gained popularity with the rise of cloud data warehouses and data lakes (e.g., Snowflake, BigQuery, Amazon Redshift, Databricks on data lakes) which can store vast amounts of raw data cheaply and process it at scale. Instead of doing heavy lifting before loading, you load everything and then selectively transform as needed.
Use Cases and Rationale: ELT is suitable when you want to preserve raw data for flexibility, and when your target system is powerful enough to handle transformations on potentially huge data sets. Cloud systems often separate storage and compute and can scale up compute for heavy transforms, so it can be efficient to leverage that rather than an external ETL engine. ELT also aligns with “schema-on-read” philosophies: store the raw data first, then apply schema and analysis when you read it. For instance, a data lake might ingest raw JSON logs from various sources; data engineers then use Spark/SQL to parse and refine that data into tables for analysis. But if later you realize you need a different field from the raw JSON, you can parse it because the raw JSON is still there.
Benefits: One major advantage is agility and completeness. Because ELT loads all the raw data (or at least more of it than a curated ETL would), analysts and data scientists can later decide to transform it in new ways. You don’t lose potentially useful information by pre-aggregating or filtering it out. In other words, ELT can enable a “data lake” where all data is kept and transformations are done per use case. Another benefit is simplicity of extraction: you often just dump source tables to the target without many modifications, which can simplify the pipeline (the complexity shifts to transformation queries in the warehouse). Additionally, ELT eliminates the need for a separate staging server because raw data is simply loaded directly to the target storage. Modern warehouses can handle semi-structured data and have features for transformation (like user-defined functions, etc.), making them suitable transformation platforms.
Drawbacks: ELT can result in storage of a lot of raw data that might never be used directly. This can incur storage costs (though storage is relatively cheap now) and can raise compliance questions (you're now storing sensitive data in raw form in the warehouse/data lake, potentially before masking it). Another issue is that if not managed, the warehouse can become a “data swamp” with raw data that is not well understood or documented. It requires strong data governance to keep track of what raw data is loaded and how to transform it correctly. Performance of queries might suffer if users directly query raw data (which might be messy or not optimized) – hence ELT usually involves creating transformed “views” or tables anyway, it’s just done inside the warehouse.
ETL vs ELT Differences: In summary, the key difference is where the Transform happens. ETL transforms data before loading into the analytics store, often using an external engine, while ELT pushes data in raw and uses the target’s power to do transforms later. ELT leverages the scalability of modern systems to handle transformations on large raw data sets, something not as feasible in the past. However, as noted by Integrate.io’s comparison, there are trade-offs in compliance and expert availability (ELT is newer and experts/tools are still catching up, whereas ETL is mature).
A common approach is to do a bit of both: for instance, some lightweight cleaning might occur before loading (especially if needed to even parse the data), and then heavy transformations occur after load. Many pipelines load raw data as separate schema or tables (like a “raw” schema vs “refined” schema in the warehouse) – data engineers then write SQL transformations to populate the refined schema from raw. This way, raw is always available for reprocessing if needed.
Example: A practical example: A company collects clickstream logs. In an ETL scenario, they might parse those logs on a Hadoop cluster and load only aggregated user sessions to a warehouse. In ELT, they might instead load all the raw log lines into a cloud data lake (e.g., in Parquet files on S3 or directly into a Snowflake table) and then run queries to aggregate sessions on demand or to create derived tables. If later they need a different aggregation or want to apply machine learning, having the raw events is a boon – they can transform them as needed without going back to source.
Both ETL and ELT have their place. Often, regulatory constraints might favor ETL (to strip out data early). Big data analytics and fast iteration favor ELT. ETL is better for complex transformations on smaller data and compliance (pre-filtering), while ELT is better for handling huge volumes and varied data in a scalable way. As cloud data platforms evolve, ELT (or even “no transform, just load everything”) is increasingly common.
3.3.4 Change Data Capture (CDC)
Change Data Capture refers to techniques for identifying and capturing only the changes in data (inserts, updates, deletes) from a source, rather than extracting full data dumps repeatedly. CDC is especially used with databases: instead of re-reading an entire table to see what’s new, CDC methods will capture the deltas since the last ingestion. These changes can then be ingested into a target system to keep it in sync in near real-time.
How CDC works: Many databases have internal logs (like write-ahead logs, binlogs, redo logs) that record every change to the data (for recovery purposes). CDC tools tap into these logs to read the sequence of changes. For example, if a record is inserted in the source DB, a CDC process sees that insert event and propagates it to the target (perhaps through a message or applying the same insert on the target). Similarly for updates and deletes. There are a few implementations: some relational databases (Oracle, SQL Server) have built-in CDC features that publish changes. There are also open-source tools like Debezium that can connect to DB logs and stream changes. In modern data engineering, CDC is a key to building real-time data pipelines from traditional databases.
Use Cases: CDC is widely used for replicating operational data to a data warehouse or data lake in real-time or near-real-time. For instance, an e-commerce site wants its analytics database to be only a few seconds behind the production orders database – CDC can stream new orders as they occur. Another use is feeding streaming systems: e.g., capturing changes in a customer database and sending them to a Kafka topic for downstream consumers (like a caching system or search index updater). CDC is also used in microservices architectures to maintain data consistency between services (one service’s DB changes are propagated to others that need that data). In cloud migration, CDC can help continuously replicate data from on-prem to cloud until cutover.
Benefits: The main benefit is efficiency and low-latency synchronization. Instead of bulk copying entire tables, you only move the minimal information (the changed rows). This reduces data transfer volume and can often run with minimal impact on the source (since it reads from a log). It enables what’s essentially incremental ingestion, which is vital for keeping systems in sync without huge batch jobs. CDC thus allows scaling to large databases that would be impractical to fully dump frequently. Another benefit is timeliness: CDC can deliver changes in near real-time, supporting up-to-date analytics and reactive applications.
Challenges: Implementing CDC can be complex. It depends on database technologies and often requires careful setup (enabling logs, etc.). There’s also the issue of schema changes: if the source schema changes (new column added), the CDC pipeline needs to handle that (which can be tricky if not designed for schema evolution – more on this challenge in Section 3.4.1). Also, ensuring exactly-once delivery of changes to the target is a challenge – you don’t want duplicates or missing events. Many CDC systems include a sequence or offset to order changes. Additionally, if a lot of changes occur in a short time, the CDC consumer must keep up or risk lagging behind. Proper error handling and monitoring is needed – e.g., if the target is down, do you buffer changes, etc.
Another challenge: CDC typically reproduces the data changes exactly, but some analytics might want a different representation (like slowly changing dimensions Type 2, where you keep history of changes). On ingestion, one might convert CDC events into historical versioning in the warehouse. This requires logic (e.g., interpreting an update event as closing one version and starting another). Tools or frameworks can assist, but it's a design consideration.
Example: Suppose a customer record is updated in the CRM (address changed). A CDC pipeline would capture that UPDATE event. If the target is a data warehouse, you have options: apply it as an update (so the warehouse has the latest address), or keep both old and new (historical record). This depends on the analytical needs. CDC provides the raw change (old address -> new address), and you decide how to handle it. Databricks (2025) explains this in terms of Slowly Changing Dimensions (SCD) – either keep only latest (Type 1) or keep history (Type 2). SCD Type 2 means each change results in a new row with a version or timestamp. Many ingestion pipelines using CDC implement such logic so that the data lake contains all versions of data (useful for audit or time travel in analysis).
In summary, CDC is a powerful technique to achieve real-time data ingestion from systems that were traditionally batch-oriented. It fits into streaming ingestion as one method of pulling changes continuously. By capturing only what changed, businesses can build fresh data repositories without reprocessing everything, which is crucial for modern low-latency analytics.
3.3.5 Message Queues and Streaming Platforms
Message queues and related technologies (often called streaming platforms or event streaming systems) play a crucial role in data ingestion architectures, particularly to decouple sources and targets and to handle streaming data. Examples include Apache Kafka, RabbitMQ, Amazon Kinesis, Google Pub/Sub, and others.
A message queue is a system that accepts messages (data events) from producers and holds them (in memory or on disk) until consumers retrieve them. It typically guarantees delivery (at least once or exactly once depending on configuration) and can buffer bursts of data. A pub/sub (publish-subscribe) system like Kafka allows multiple consumers to get the same stream of messages, and it retains messages for a certain period allowing consumers to read at their own pace. These systems are distributed and can scale to high throughput, making them popular for large-scale data ingestion.
Role in Data Ingestion: Using a message queue or stream, data from various sources (applications, sensors, log collectors, CDC pipelines) is published as events into the queue/topic. Downstream services or pipelines then subscribe or pull from the queue to process or store the data. This decoupling means the source doesn’t have to directly interact with the database or target store – it just hands off to the queue. The queue can buffer data if the target is slow or temporarily unavailable, improving resilience. It also allows one source’s data to feed multiple targets (for example, a click event might go to both a real-time monitoring system and a batch storage, via different consumers reading the same queue).
Use Cases: Virtually any scenario that involves streaming data or integration of multiple systems can benefit. For instance:
In IoT, devices publish sensor readings to a cloud IoT Core or Kafka topic; from there, one consumer might store raw readings to a data lake, another might do real-time analysis for alerts.
In microservices, when one service has an event (like “order placed”), it puts it on a queue so that other services (shipping, billing, analytics) can consume that event and react, without being tightly coupled.
In data pipelines, a message queue can serve as an ingestion buffer. Logstash (in ELK stack) can push logs into Kafka; then multiple consumers (maybe Spark jobs, or an Elasticsearch indexer) read those logs. Or a CDC pipeline writes DB changes to a Kafka topic, from which a consumer updates a search index and another consumer updates a warehouse.
Advantages:
Decoupling: Producers and consumers don’t need to know about each other. They just need to know the queue. This makes the system more modular and scalable (browser search result suggests Kafka is often used not just as a queue but as a high-throughput event log, highlighting its use in decoupling big data ingestion).
Backpressure handling: If a consumer is slow or down, the queue can retain messages until it catches up, instead of losing data.
Scalability: Systems like Kafka are designed for high throughput (millions of messages per second) and can be scaled horizontally. They also provide durability (messages can be replicated across nodes).
Multiple consumers: With pub/sub, one event can fan out to many systems. This is efficient compared to each system querying the source independently.
Streaming processing: Some frameworks (Kafka Streams, Spark Streaming, Flink) can operate directly on these queues to do real-time computation, effectively the queue is the ingestion and processing substrate.
Challenges:
Complexity: Introducing a message broker adds another component to manage. It requires configuration (like deciding on retention periods, topic partitioning) and operational monitoring.
Data ordering and consistency: In distributed queues like Kafka, events are partitioned (by key) to scale. Events with different keys could be processed out-of-order relative to each other. Designing so that ordering guarantees (if needed) are met can be tricky.
At-least-once vs exactly-once: Many queues guarantee at-least-once delivery (meaning duplicates are possible). Handling duplicates idempotently on the consumer side is often necessary. Newer developments allow exactly-once in Kafka Streams, but it’s a nuance to consider.
Latency: While usually small, there is some latency added by going through a broker. For most uses this is acceptable (sub-second), but extremely latency-sensitive apps might avoid it. However, for ingestion, a slight delay is usually fine given the benefits.
Schema management: If events have schemas (say JSON structures), managing how changes in schema propagate is important (using something like a Schema Registry with Kafka to ensure producers and consumers agree on data format).
Example Architecture Pattern: A common pattern is an “ingest funnel”: multiple producers -> queue -> processing -> storage. For instance, Netflix open-sourced their Keystone pipeline where Kafka is used to ingest event data, after which it’s processed and stored in a data warehouse. Another pattern is using message queues for buffering batch loads: a system writes data to a queue quickly, and a batch job reads from the queue and writes to DB in bigger chunks, smoothing out load on the DB.
Apache Kafka is particularly notable as it blurs the line between messaging and storage: it’s often called a “distributed log”. Companies use it as a central data bus. For example, Kafka is used at LinkedIn, Uber, etc., to ingest all kinds of event data and distribute to various systems. Kafka can also serve both streaming and (with retention) a replayable log (so if a consumer goes down, it can catch up from where it left off).
Message Queues vs Traditional ETL: In a sense, queues enable a shift from batch ETL to streaming pipelines. Traditional ETL might query a DB and load results; a queue-based pipeline streams changes continuously. This goes hand-in-hand with CDC (for example, Debezium streams DB changes into Kafka topics). Then one can have an “always up-to-date” data pipeline, rather than periodic big loads.
In conclusion, message queues and streaming platforms are critical components in modern data ingestion architectures to achieve scalable, real-time, and decoupled pipelines. They provide the infrastructure backbone for many of the streaming and CDC solutions discussed. Using them appropriately leads to more robust and flexible ingestion systems – but they require careful management and a good understanding of distributed messaging semantics.