5.3: Univariate Analysis Techniques
- Page ID
- 48059

\( \newcommand{\vecs}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\( \newcommand{\vecd}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash {#1}}} \)
\( \newcommand{\dsum}{\displaystyle\sum\limits} \)
\( \newcommand{\dint}{\displaystyle\int\limits} \)
\( \newcommand{\dlim}{\displaystyle\lim\limits} \)
\( \newcommand{\id}{\mathrm{id}}\) \( \newcommand{\Span}{\mathrm{span}}\)
( \newcommand{\kernel}{\mathrm{null}\,}\) \( \newcommand{\range}{\mathrm{range}\,}\)
\( \newcommand{\RealPart}{\mathrm{Re}}\) \( \newcommand{\ImaginaryPart}{\mathrm{Im}}\)
\( \newcommand{\Argument}{\mathrm{Arg}}\) \( \newcommand{\norm}[1]{\| #1 \|}\)
\( \newcommand{\inner}[2]{\langle #1, #2 \rangle}\)
\( \newcommand{\Span}{\mathrm{span}}\)
\( \newcommand{\id}{\mathrm{id}}\)
\( \newcommand{\Span}{\mathrm{span}}\)
\( \newcommand{\kernel}{\mathrm{null}\,}\)
\( \newcommand{\range}{\mathrm{range}\,}\)
\( \newcommand{\RealPart}{\mathrm{Re}}\)
\( \newcommand{\ImaginaryPart}{\mathrm{Im}}\)
\( \newcommand{\Argument}{\mathrm{Arg}}\)
\( \newcommand{\norm}[1]{\| #1 \|}\)
\( \newcommand{\inner}[2]{\langle #1, #2 \rangle}\)
\( \newcommand{\Span}{\mathrm{span}}\) \( \newcommand{\AA}{\unicode[.8,0]{x212B}}\)
\( \newcommand{\vectorA}[1]{\vec{#1}} % arrow\)
\( \newcommand{\vectorAt}[1]{\vec{\text{#1}}} % arrow\)
\( \newcommand{\vectorB}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\( \newcommand{\vectorC}[1]{\textbf{#1}} \)
\( \newcommand{\vectorD}[1]{\overrightarrow{#1}} \)
\( \newcommand{\vectorDt}[1]{\overrightarrow{\text{#1}}} \)
\( \newcommand{\vectE}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash{\mathbf {#1}}}} \)
\( \newcommand{\vecs}[1]{\overset { \scriptstyle \rightharpoonup} {\mathbf{#1}} } \)
\(\newcommand{\longvect}{\overrightarrow}\)
\( \newcommand{\vecd}[1]{\overset{-\!-\!\rightharpoonup}{\vphantom{a}\smash {#1}}} \)
\(\newcommand{\ket}[1]{\left| #1 \right>}\)
\(\newcommand{\bra}[1]{\left< #1 \right|}\)
\(\newcommand{\braket}[2]{\left< #1 \vphantom{#2} \right| \left. #2 \vphantom{#1} \right>}\)
\(\newcommand{\braopket}[3]{\left< #1 \vphantom{#2}\vphantom{#3} \right| #2 \vphantom{#1}\vphantom{#3} \left| #3 \vphantom{#1}\vphantom{#2} \right>}\)
\(\newcommand{\qmvec}[1]{\mathbf{\vec{#1}}}\)
\(\newcommand{\op}[1]{\hat{\mathbf{#1}}}\)
\(\newcommand{\expect}[1]{\langle #1 \rangle}\)
\(\newcommand{\dfn}[1]{\emph{\textbf{#1}}}\)
Univariate Analysis Techniques
A natural first step in EDA is univariate analysis, which examines each variable individually. The purpose of univariate analysis is to understand the distribution and key properties of each field in the dataset. For each variable, the EDA process asks: What are the typical values? What is the spread? Are there outliers or unusual values? The answers differ based on the type of variable (also called measurement level or dimension vs. measure in data visualization terminology). For a numerical variable (a measure), we examine its statistical distribution; for a categorical variable (a dimension or factor), we look at the frequency counts of each category.
Summary Statistics:
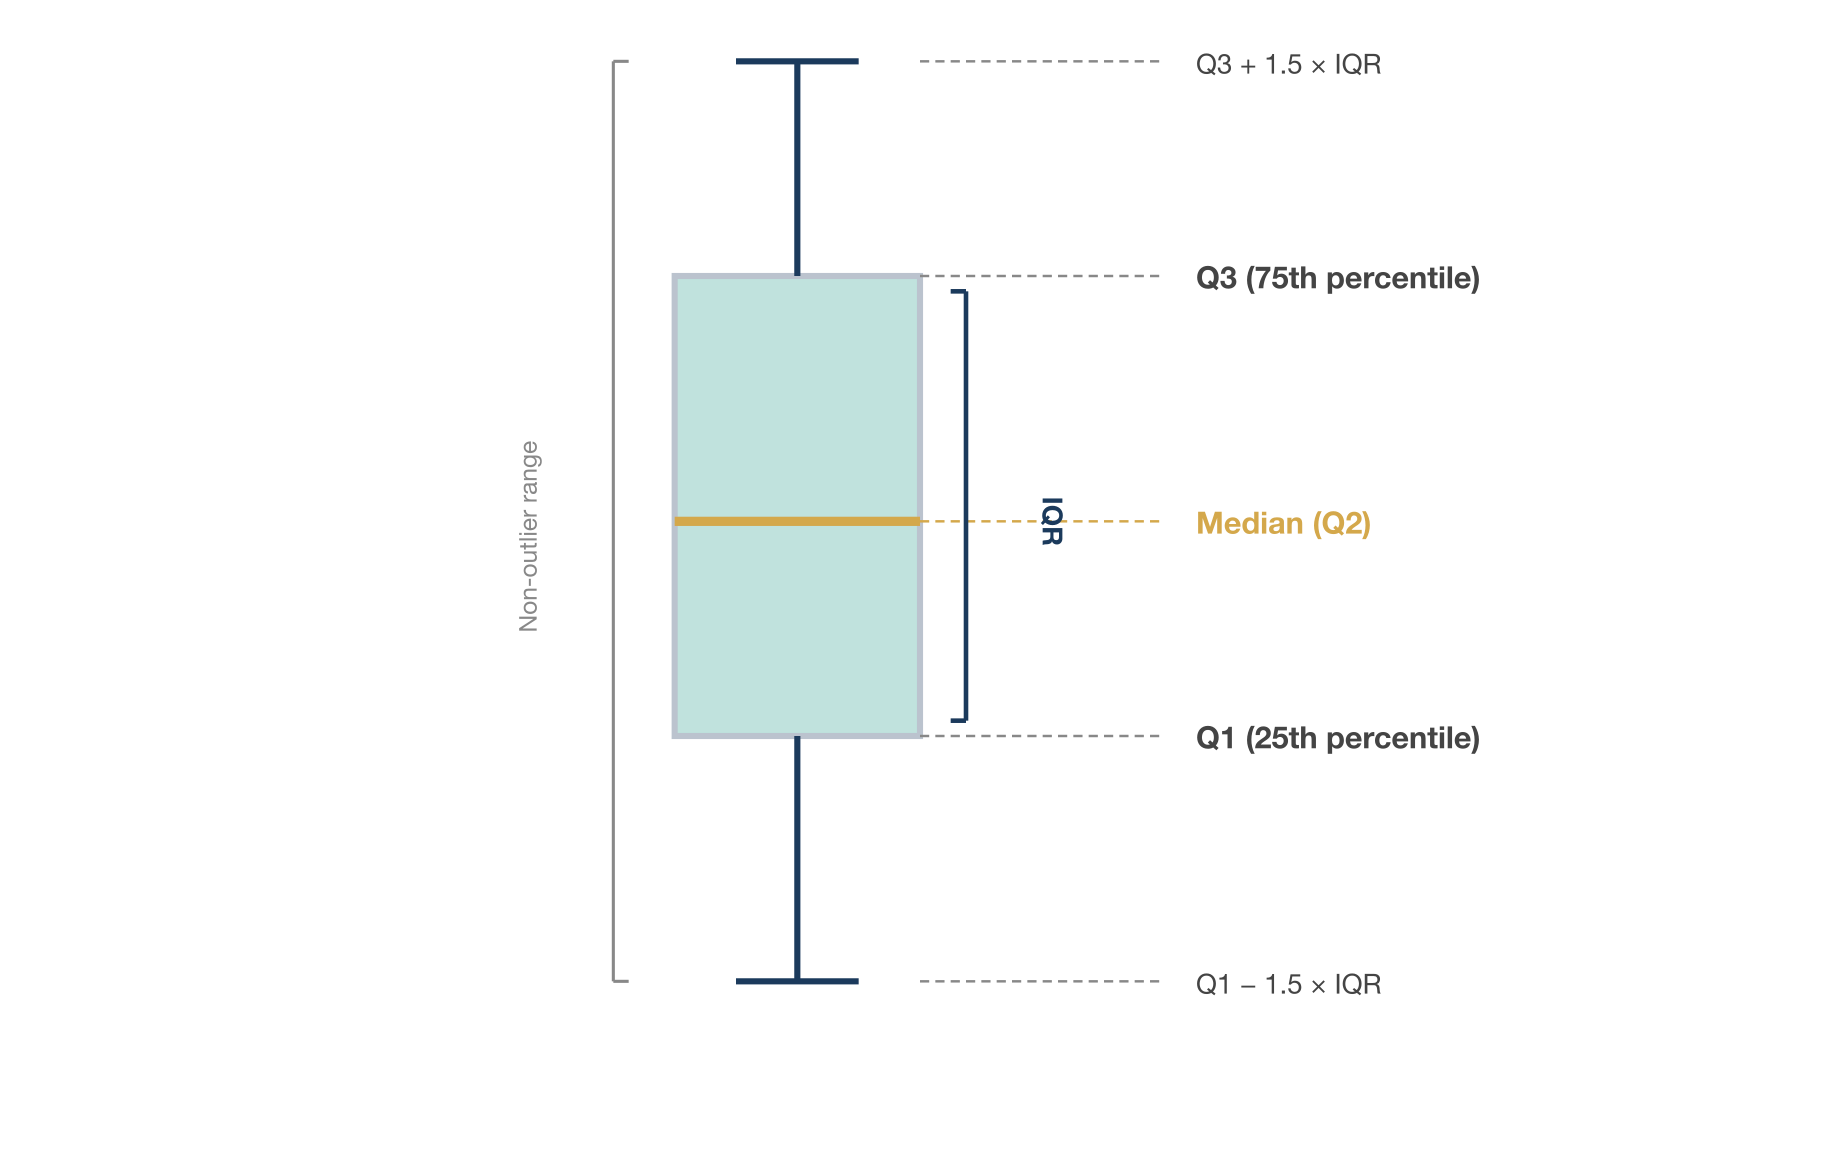
A quick way to summarize a numeric variable is to compute its descriptive statistics. Common summary measures include the mean (average), median (middle value), mode (most frequent value), standard deviation (which quantifies spread or variability), range (min to max), and the quartiles (which give the five-number summary along with min/max). For example, using a tool like pandas in Python, one can call df.describe() to get the count, mean, std, min, quartiles, and max of every numeric column in a dataset. These statistics concisely describe the central tendency and dispersion of the data. Tukey emphasized the importance of robust summaries like the median and interquartile range (IQR) over mean and full range, because they are less sensitive to outliers and skewed distributions. The IQR (the width of the middle 50% of data) is especially useful; it is the basis for the box plot and for a common outlier detection rule (often, points 1.5×IQR beyond Q1 or Q3 are flagged as outliers). By reviewing summary stats, an analyst can quickly grasp if a variable is, say, highly skewed (e.g., mean much larger than median suggests right-skew), or if there are any impossible or suspicious values (like a negative value for a field that should only be positive).
Distribution Plots:
While summary statistics are helpful, it is crucial to visualize the distribution of each numeric variable to truly understand it. Two primary visual tools for this are histograms and box plots. A histogram divides the data into bins and shows how many observations fall into each bin, giving a sense of the shape of the distribution (uniform, bell-shaped, skewed, multi-modal, etc.). The choice of bin width can reveal different features: a coarse binning might smooth out minor variation, whereas a fine binning might expose subtle patterns (or just noise, if overdone). A box plot (or box-and-whisker plot) provides a compact depiction of distribution: it shows the median as a line, the IQR as a box, and “whiskers” extending to data within 1.5×IQR of the quartiles, with individual points plotted beyond that as outliers. Box plots immediately highlight the median, the spread, and any outliers in a variable. They are especially useful for comparing distributions across many groups or variables side by side.
For categorical variables, one would typically use frequency tables or bar charts. A frequency table simply counts how many observations fall in each category; a bar chart visualizes these counts (or percentages). This helps identify the mode category and whether the data is balanced or dominated by a few categories. For instance, a bar chart of a "Gender" variable may show nearly equal counts of male and female, or a disparity if the dataset is unbalanced.
Example – Distribution of a Numeric Variable: Consider a dataset of restaurant bills and tips (a classic example from the literature on EDA). One numeric variable is the tip amount a customer leaves. We can plot a histogram of tip amounts to see how tips are distributed.
From a single histogram or box plot, we also gain information on outliers. In the tips example, if someone left a \$10 tip on a \$15 bill, that would show up as a point far to the right, detached from the main distribution. Noting such outliers would prompt us to ask if those are data entry errors, or genuine but rare occurrences, or if perhaps the context differs (maybe a large party). In univariate EDA we simply record these facts without yet drawing conclusions – EDA is about observation. For each variable we’d ideally note: distribution shape, any anomalies (outliers, multiple modes), central values, and spread.
It's worth reiterating the advice often given to analysts: always graph your data before computing extensive statistics. Patterns like multi-modality or a long tail are often much more apparent visually. Numerical summaries alone might not convey if a distribution has two clusters (bimodal) – but a histogram will show two peaks clearly. EDA encourages this visual inspection as a first resort.